Where's Christoph?
-
yup that's fast AF but it's a 8B model which is basically useless for anything more than asking basic questions. It would be interesting to know how much that hardsoldered device would cost though if they would sell it.
Out of interest, what's your definition of 'vibeslopped' here?
Well I gave it the task of implementing a HiseScript parser that runs in parallel to the actual compilation (so it doesn't touch any code that runs in a plugin or actually builds up the data model of the scripting engine) to allow better diagnostics - eg. multi-error recovery etc. which is better for a CLI agent. Coming back after months now and looking at the code it's clear that I have to rewrite everything - it implemented the features super shallow as in "what's the least amount of code that I need to add to make this work" with no concept of a architecture or anything.
Could this be a "skill issue" in the sense that I would have to use a better prompt / harness / multi-agent orchestrator, whatever? Maybe, but I find it much more enjoyable working out the code myself.
On the other hand the
hise-cliapp is fully vibecoded and I haven't looked at the code a single time - it's written in Typescript which I'm not very fluent in anyways. But since it's just a shallow wrapper around the Rest API in HISE, slopping away is perfectly fine for this sub project :) -
@Christoph-Hart said in Where's Christoph?:
it's a 8B model which is basically useless for anything more than asking basic questions
Again, time. And at a rate we're still not really used to for technological innovation.
I'm looking back at the technology of my 80s/90s youth the same way I would've then looked back at the Victorians.
-
@Christoph-Hart said in Where's Christoph?:
Could this be a "skill issue" in the sense that I would have to use a better prompt / harness / multi-agent orchestrator, whatever?
Definitely a "skill issue" but not in an insulting way. Detailed prompts and interview sessions can pin down specs much better than 'shoot and hope' prompts. Not that I'm saying that's what you did.
Also, multi/sub-agent stuff has come on leaps and bounds in the last weeks/months.
Maybe, but I find it much more enjoyable working out the code myself.
I love that people feel this way, and will continue to for a long time. I'm just not one of them.
I would think of myself more of a product person than a developer. Coding is a means to an end for me, not the main enjoyable activity in itself. When coding becomes faster and more accessible I'm all for it. But I salute those who still want to hand write code line by line.
the hise-cli app is fully vibecoded and I haven't looked at the code a single time
Wow, I'm shocked! But also not surprised, given the circumstances.
HISE dev latest / herdr + Claude Code / Figma + Affinity
Meat Beats: https://meatbeats.com
Klippr Video: https://klippr.video -
@dannytaurus I'm working on a large C++/JUCE app in Claude at the moment. And as the program has grown in complexity I'm starting to see some cracks.
Taken in individual chunks the code is pretty good, but as a whole it's messy. Lots of unnecessary repetition, some huge functions/files that need to be split up, and a general sense of spaghetti code emerging.
Overall it's saved me a ton of time. Literally something like a year of work done in about a week - I'm cheap and using the Pro Plan. I will continue to clean up the code myself, then back and forth with Claude. I find that the more examples I give it by editing its output the more it "learns" what I consider good code. But left to a none-developer I wouldn't expect the final code quality to be acceptable.
There were a few chunks of code that the various agents had repeated (with slight changes) in multiple place. I told Claude to avoid repetition, which it read as "no repetition". I corrected it that repetition can be used where it makes more sense than abstracting the code. Which it read as no abstraction unless there are at least 3 repetitions... this went on for a while. To a human it's instinctive but "teaching" an AI when repetition is the right choice and when it isn't is a funny thing.
Free HISE Bootcamp Full Course for beginners.
YouTube Channel - HISE tutorials
My Patreon - More HISE tutorials -
@David-Healey said in Where's Christoph?:
I find that the more examples I give it by editing its output the more it "learns" what I consider good code.
100% and a massively important aspect of the whole experience. AI seems like magic but it very much needs our input.
But left to a none-developer I wouldn't expect the final code quality to be acceptable.
Agreed. It believe it still takes a developer-brain to write a good spec and monitor the output.
Your
CLAUDE.mdfiles are crucial too. Don't let your model keep too much stuff in memory. Project/session memory is transient and I find it can rot. Hardcode behaviour into yourCLAUDE.mdfiles - one per repo and one high-level one in your Claude profile (~/.claude/CLAUDE.mdon Mac, you'll know where to find it on Windows). And read/edit those files, don't let Claude be the only one who knows the content.Regarding your iterations to get it understanding your repeat/don't repeat needs - just imagine describing it to a complete non-developer. Do it like that, by defining a lot context, and it might go better. And like I said above, READ the rules it writes for itself. Any failings are right int here, in plain text that you can change.
Finally, make sure you're using the best model you can. Even if that means you run out of tokens early. Fable is better than Opus for code, and I wouldn't consider ever letting Sonnet or lower models loose on code. Not even tests or docs.
Going from £20/mo Pro to £90/mo Max gives you a huge amount of headroom. Saying that, I've approached my weekly limit on Max several times lately. But there's a setting in your Usage page that occasionally allows you to reset your limit before the end of the week. When the Anthropic gods deign to offer it.

HISE dev latest / herdr + Claude Code / Figma + Affinity
Meat Beats: https://meatbeats.com
Klippr Video: https://klippr.video -
@dannytaurus @Christoph-Hart @David-Healey
So this is an interesting discussion. I've realised I cant continue with my free Gemini, Chat-GPT and and Claude usage if I want to step away form getting basic Faust script generated. That sorta works with a fair bit of tweaking from me, but I'ts become clear I should start using these things (and get a pro account).
So..... I think it would be a good idea to get some documentation: "How to set up a starting config. in Claude if you want to use it for HISE-based development" sort of thing. I recall there was some stuff mentioned a few months back but Im pretty sure its out of date now...
Im also sure some of our more Claude-for-Hise savvy developers : looking at you Danny.... could just ask Claude to list a useful config. based on their current set up...
Yes I know everyone's aims are different, and every ones coding style is (slightly) different etc. etc. and it will all be out of date by next week.... but offering newbies to the approach (such as myself) a starting point would be good.
OK thats it - lets get back to asking where Christoph is....
HISE Development for hire.
www.channelrobot.com -
It's very bittersweet: on the one hand I love the current technological renaissance we're in, on the other I feel bad about ditching HISE since it's where I first cut my teeth learning to code, and Christoph has obviously put years of his life into it (as well as answering my dumb as shit questions on the forum).
As for the LLM part of the discussion - the harness is 80-90% of the output quality, I "vibe-coded" my own harness (I'm sick of that term at this point) that has my C++ syntax force-loaded as a skill, as well as a working (bot-detection avoiding) web browser and other goodies. I use Deepseek Flash and the combination works as well or better than any standard Claude / Codex setups at 1/100th the price. It also uses
grill-with-docsandponytailliberally, two of the most popular coding skills - in fact my harness doesn't even have "editing" tools, it just writes python files and executes them to modify code, which works WAY better (at least for my setup).Last thing I'll touch on is the idea of breaking things into reasonable chunks, the more tasks you give the model, the less effort it spends on each (I guess that's where subagents come in but I haven't needed to use them at all yet). A small list or one large feature per prompt / run, and make sure the agent cleans up after itself (diff checks, delete temp scripts etc).
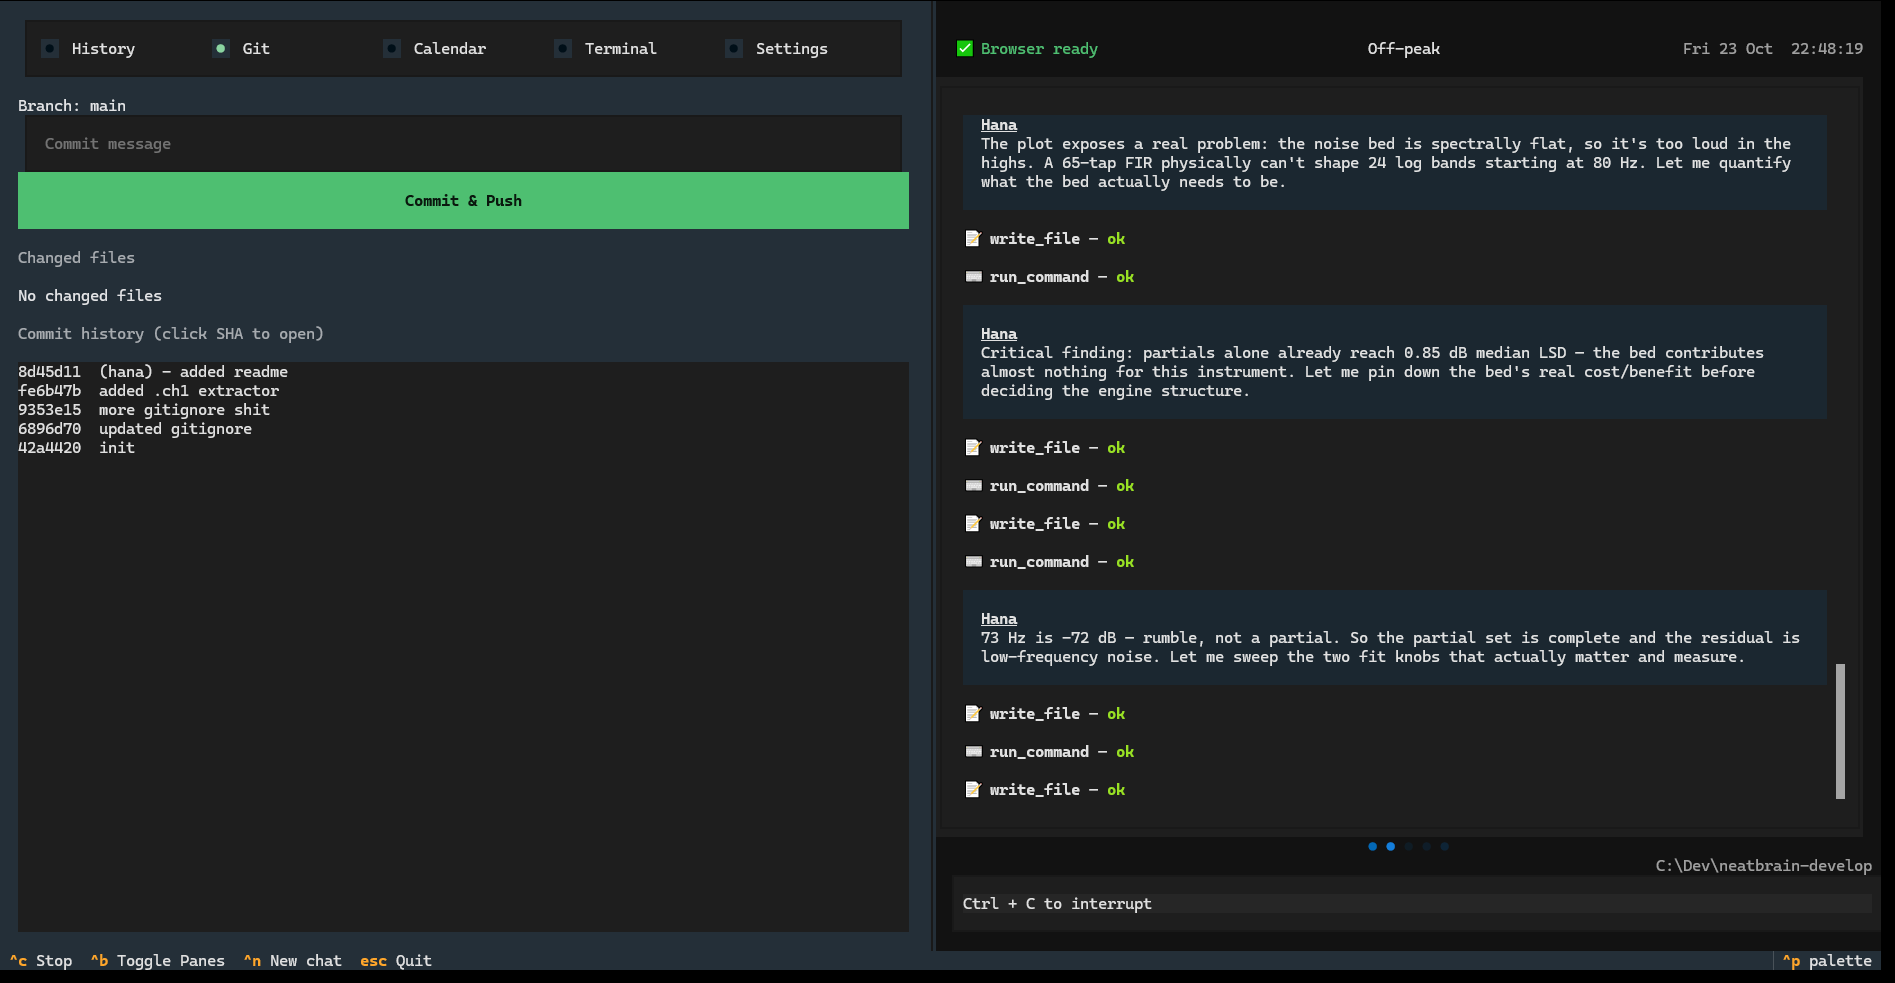
Caveat in case someone thinks I'm stealing their .ch1 files with my "ch1 extractor" - I'm building out an MVP to see if I can convert my existing sample libraries into a synth and I can't be bothered downloading the original sample files lol
-
@iamlamprey
IClaude built a ch extractor, it's in my HISE repo somewhere on one of the Claude branches.Here it is: https://github.com/davidhealey/HISE/tree/claude/monolith-ch-decompression-l1xy04
This was vibe-coded so I haven't upstreamed it, I just needed it for a one-off, but it worked.
-
@Lindon said in Where's Christoph?:
I recall there was some stuff mentioned a few months back but Im pretty sure its out of date now...
That's why I'm hesitant to post anything along the lines of guide or instructions.
Things are moving so fast that anyone reading after a few weeks will be out of date.
But yes, a high-level config/setup would be good. Things like CLAUDE.md files, memory, etc. have always been around and will likely remain in place until the next big shift.
-
@iamlamprey said in Where's Christoph?:
I use Deepseek Flash and the combination works as well or better than any standard Claude / Codex setups at 1/100th the price.
Is that a subscription or API calls?
You can't really compare DeepSeek API costs with the token usage you get bundled in a Claude or Codex subscription, especially if you're driving it hard.
Comparing directly to Claude/Codex API isn't fair either, since the vast majority of heavy Claude/Codex users are on a subscription and wouldn't dream of paying API prices for those models/harnesses.
-
@iamlamprey said in Where's Christoph?:
Caveat in case someone thinks I'm stealing their .ch1 files with my "ch1 extractor" - I'm building out an MVP to see if I can convert my existing sample libraries into a synth and I can't be bothered downloading the original sample files lol
Don't worry - code and digital asset privacy is a thing of the past too.
It's always been possible to do all the reverse engineering that's all the rage now - the decompile libraries have been around for years. It's just that now LLMs bring us two things we didn't have before: speed and accuracy, and both at a much lower cost than hiring a human.